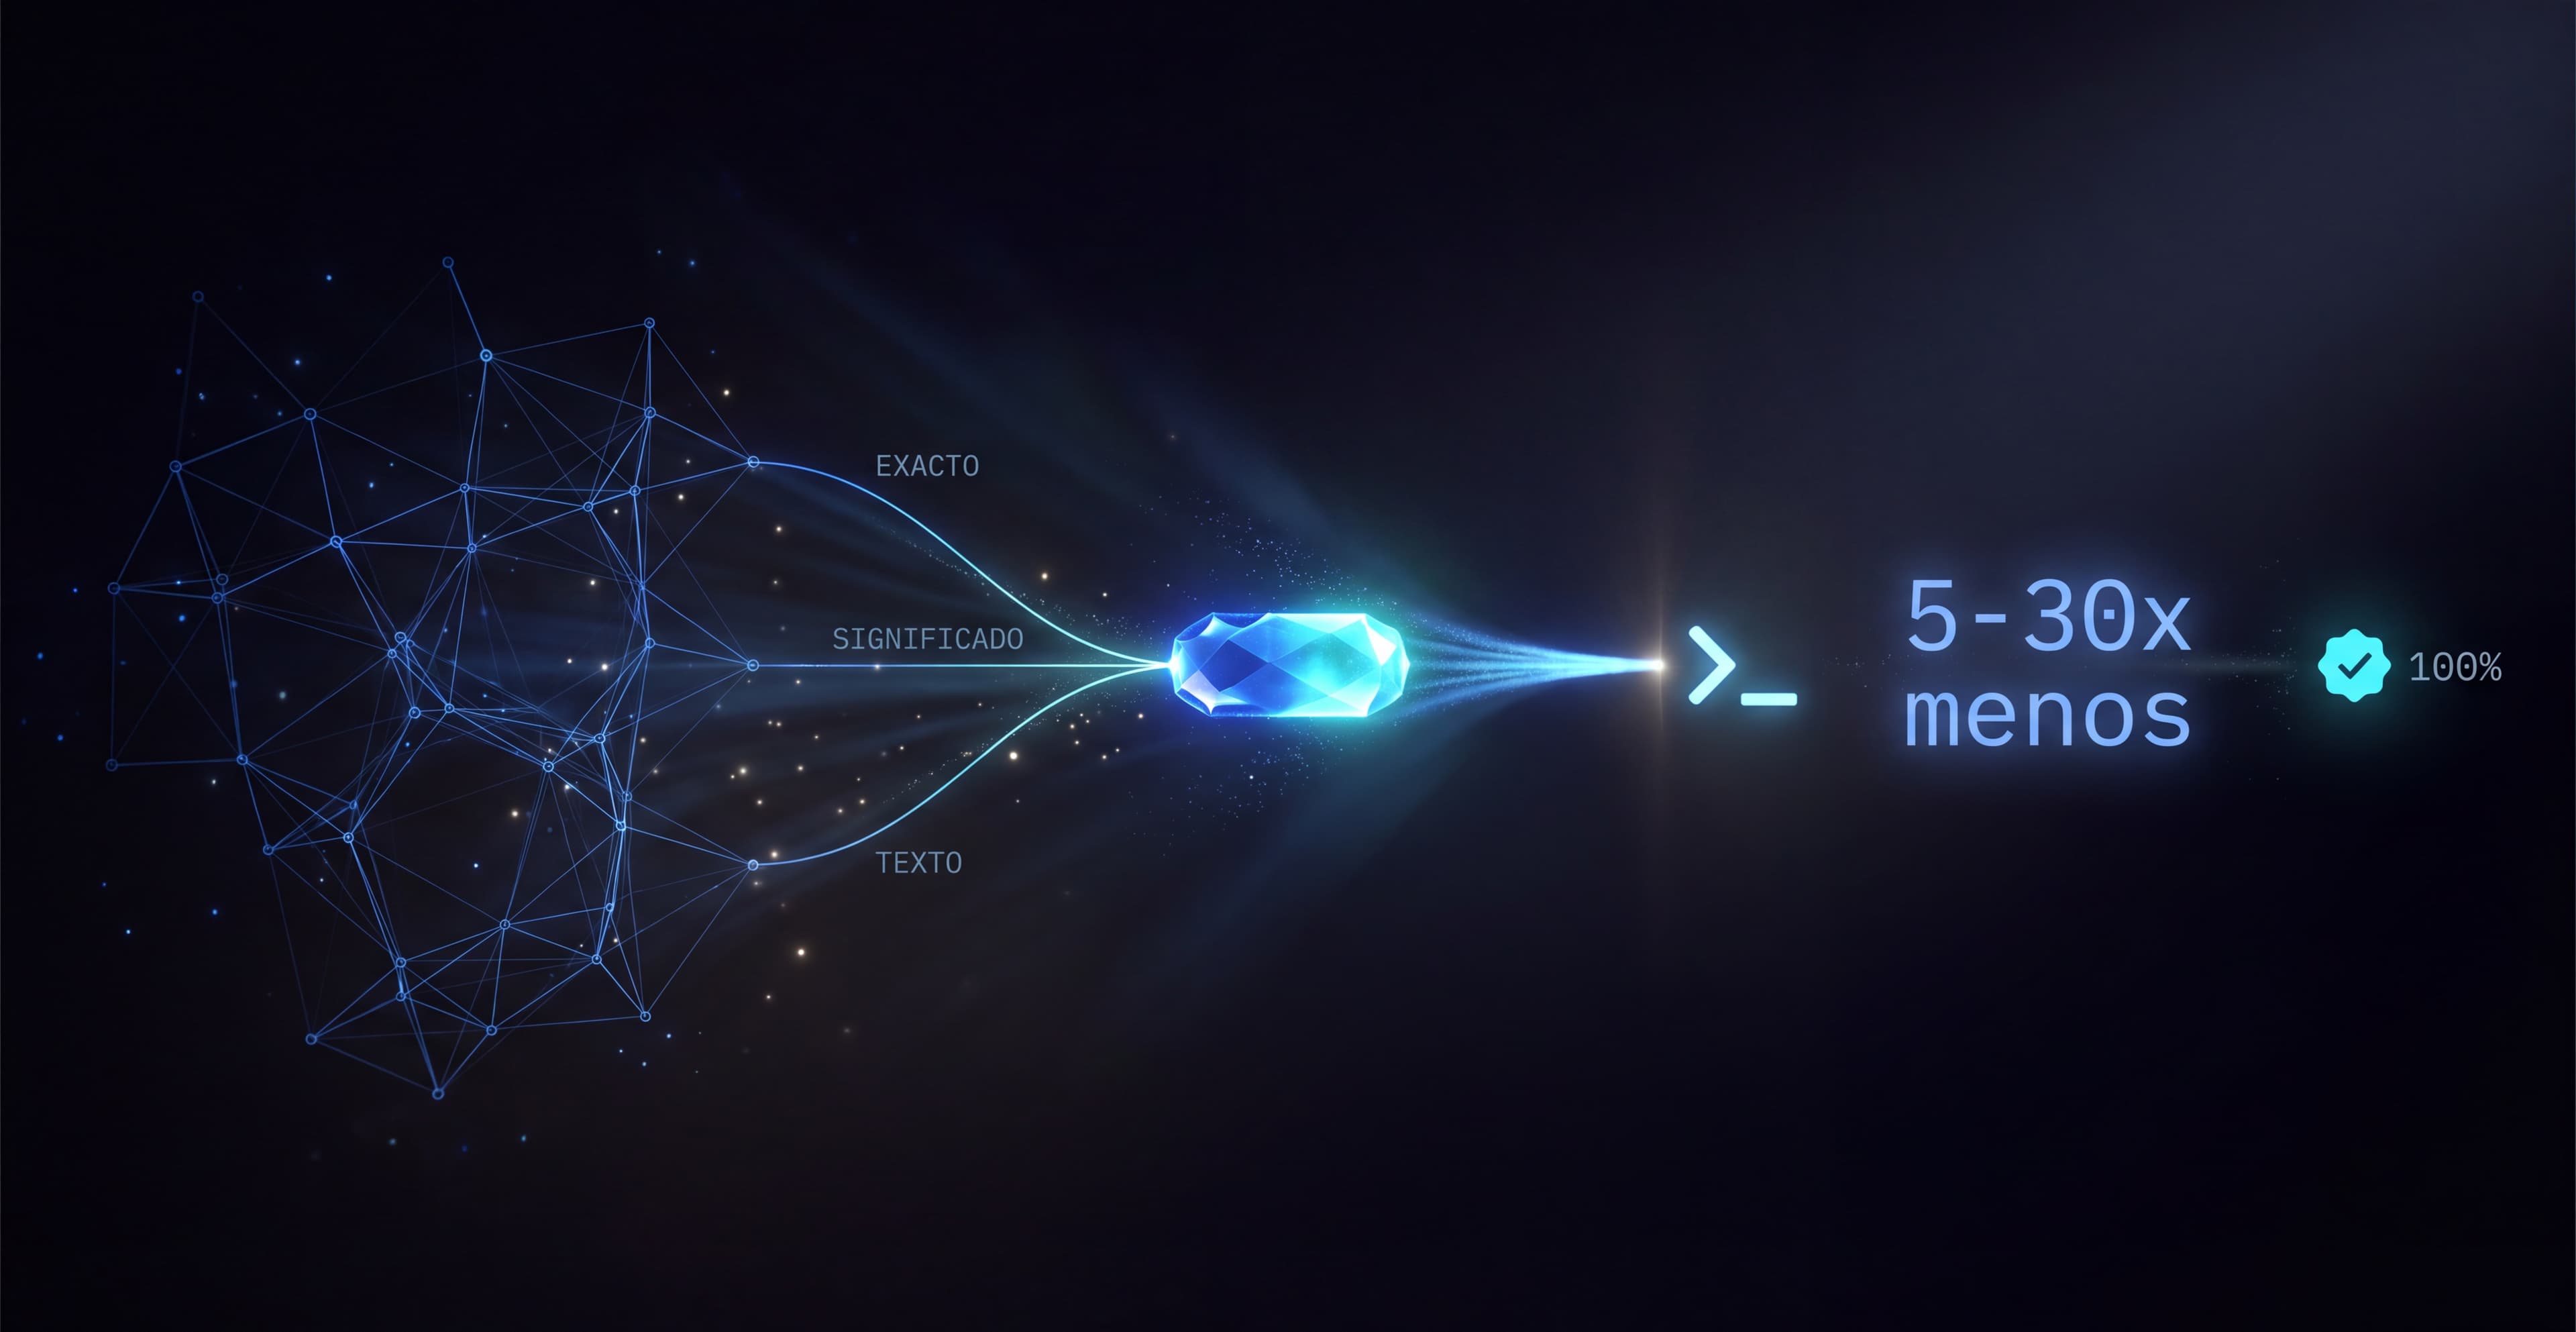
In Why chunking breaks your coding agent I explained why coding agents sometimes answer as if half the file were missing. In KC-RAG: retrieving code with structural intelligence I explained the idea behind the solution. This is the "OK, so how does it actually work?".
I'll avoid jargon as much as I can. If at some point it sounds like a lab report, I explained it badly, and I'd be glad to hear it.
The idea in one sentence
Instead of the agent opening whole files blindly and guessing which part is useful, I already have a map of all the code in advance: which functions exist, where they are, and which other functions they call. When the agent asks something, I don't give it the file. I give it exactly the piece of the map it needs, already trimmed.
It's the difference between handing someone a whole book to find one fact, or handing them the underlined page.
Step 1: build the map once
Before anyone asks anything, I go through the whole project and extract every function and every class as a complete piece, never cut in half, along with who calls whom. That's the map. It's built once, in seconds, and afterwards only the parts that change when you edit code are updated, not the whole project every time.
Step 2: search three ways at once, not one
When a question arrives, I don't trust a single search method, because each one fails differently. I search for the exact name - if you ask about verifyUser, that function shows up no matter what. At the same time I search by meaning, for when you ask in your own words rather than the literal name. And I also search by text match, the middle ground between the other two. I keep what several of the three searches point to at once, not whatever shows up first.
On top of that, I prioritise the functions that are used most within the project itself - if half the codebase calls a function, it's probably more relevant than one nobody touches.
Step 3: give it only what THAT task needs
Understanding what a function does isn't the same as getting ready to edit it, and neither is the same as writing new code from scratch. So I recognise what kind of task it is and adjust how much context I hand over: to understand, the function and a summary of what it touches are enough; to edit safely, I also include the full code of what that function uses inside; to generate something new, there's no need to see logic at all: the structure of the project.
I hand the result to the agent ready to use, with a clear instruction: "this is already here, don't open the file again". That detail, which sounds silly, is the one that saves the most money. An agent that isn't told clearly tends to reread the file "just in case", and that doubles the cost.
Step 4: before touching something, know what breaks
There's a second function, separate from search: before editing something you can ask it directly "what breaks if I touch this?" and it answers with the real list of everything that depends on that piece, with the exact file and line. It isn't the model giving an opinion or guessing: it's a walk over the map I already built, so it can't make it up.
The numbers, unvarnished
This is what changed, measured, not eyeballed:
| What I measured | How I checked it | Result |
|---|---|---|
| Size of what the agent receives per question | vs. opening the full file | 3-20% of the size → 5 to 30 times less |
| "Who calls whom" map | compared function by function with the official Python and TypeScript tools | 100% in Python · 99.9%+ in TypeScript |
| Total spend on heavy tasks | real agent, real tasks end to end | −30% |
| Total spend on normal tasks | same kind of measurement | the same, never more expensive |
| Response time | same kind of measurement | −14% on average |
I don't promise "it always saves loads" because it isn't true, and I checked that with data that said otherwise six times before landing on the version that does work. The real promise is more boring and more honest: it never costs you more, it almost never fails, and on big tasks you really notice it.
An example, to make it fully clear
You ask an agent to add Google login to a login() function that already exists.
Without the map: the agent opens the whole authentication file, searches by similarity for "login google" and gets loose pieces with no connection between them, so it can't clearly see what login() uses inside. It proposes something that breaks the existing validation because it never saw it in full. Total cost, counting the failed attempt: about 8,000 tokens.
With the map: I find login() instantly, and since I already know what it calls inside (validate password, create session), I hand it all over together, already trimmed to what's relevant. The agent sees the full logic in one go and proposes something that doesn't break anything. Total cost: about 2,500 tokens. And it works first time.
How I know the numbers are good
Because I don't believe my own numbers without checking them: the map is reviewed automatically every time I change something, compared against tools that aren't mine. If a change makes the map wrong, even slightly, that change doesn't ship. It's the same discipline I apply to this blog: if I can't check a figure, I don't write it.